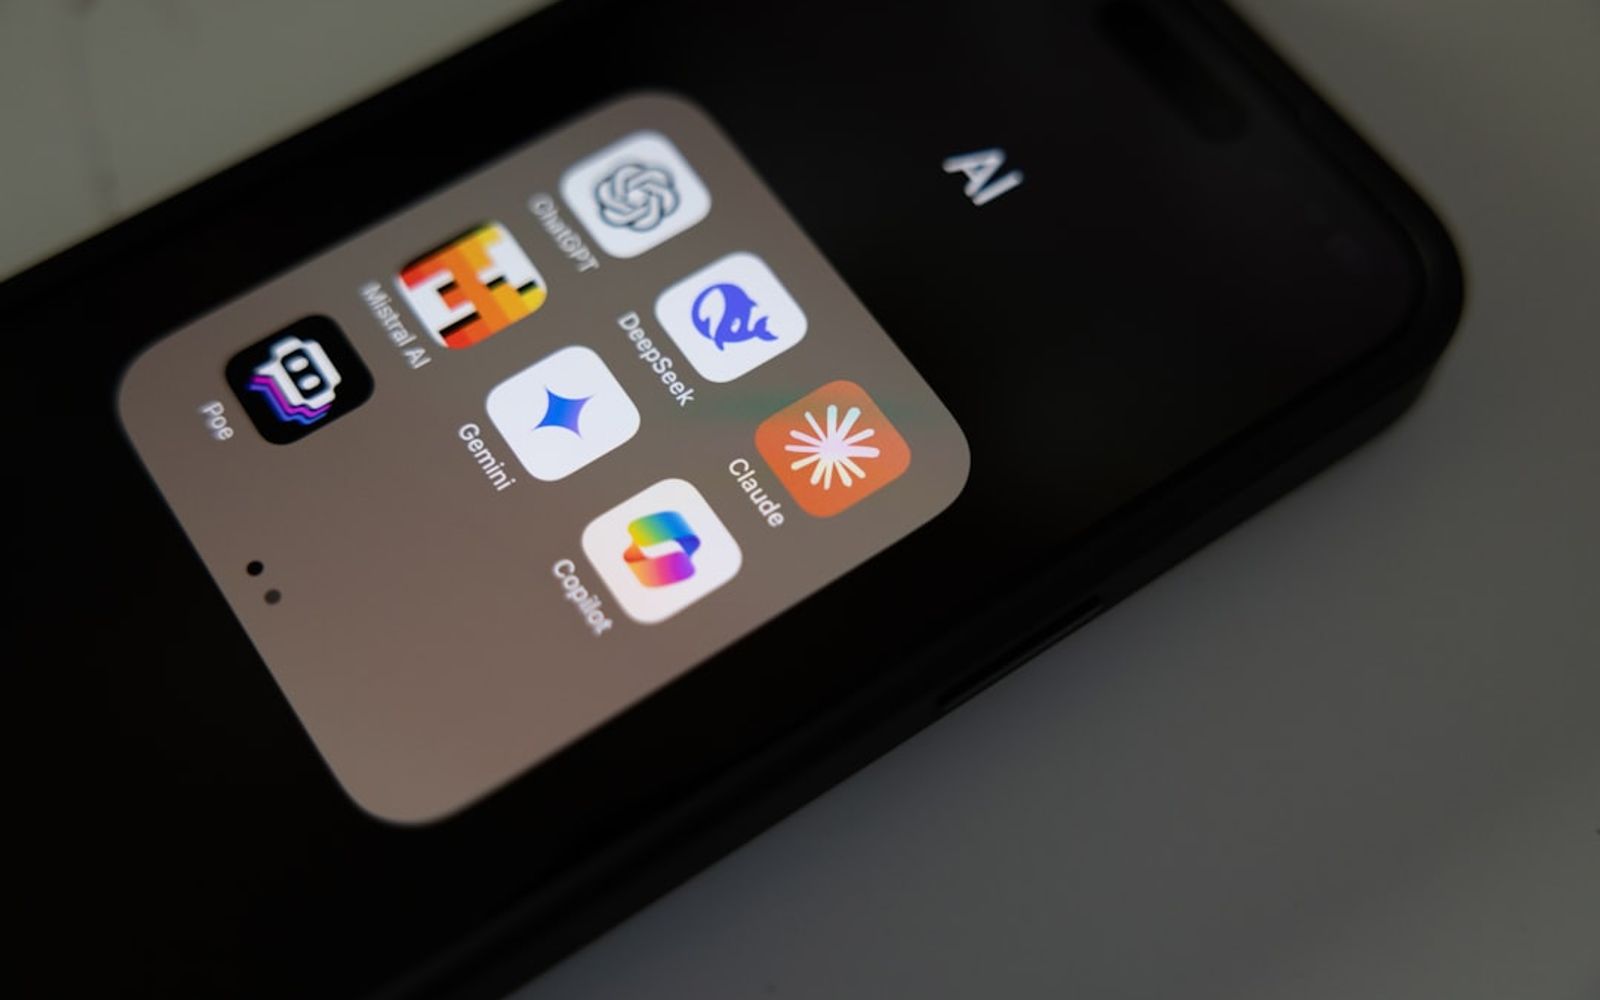
Claude, ChatGPT, or Gemini: Which AI Actually Earns Its Keep So Far?
A blind test of 134 people settled the writing debate. But the real question is which model handles your actual work.
The numbers land like a punch. In Q1 2026, independent evaluators stripped the brand names off outputs from three AI models and asked 134 people to pick their favorites. Claude won 4 out of 8 rounds, with margins between 35 and 54 percentage points on writing-specific tasks, according to TeamAI's blind test. ChatGPT placed second at 29% preference. Gemini trailed at 24%. That gap is not narrow. It's a canyon.
But here's the thing nobody says out loud: writing contests measure almost nothing about real work. A blind test on prose tells you which model sounds more human when both are given the same prompt under identical conditions. That matters if your job is drafting newsletters, grant proposals, or legal briefs. It matters less if you're debugging a Kubernetes cluster at 2AM, pulling competitive intelligence from a sea of PDFs, or trying to get an AI agent to file your quarterly taxes without hallucinating a deduction.
The three models have diverged. They no longer compete on the same axis. Claude, ChatGPT, and Gemini each optimized for a different bottleneck, and the choice between them now depends less on "which is best" and more on "best at what, exactly."
Why Claude Won the Writing War
Anthropic's Claude lineup, currently led by Opus 4.8 with Fable 5 for heavier tasks, treats language as a structure problem, not a prediction game. The model holds coherence across long documents the way a good architect holds a floor plan in their head. You can feed it 100 pages of interview transcripts and ask for a synthesis, and it will track the thread from paragraph one to paragraph one hundred without collapsing into repetition.
For long-form writing, Claude does not just perform better. It performs differently.
The prose has rhythm. Sentences vary in length and structure in ways that avoid the metronomic cadence most language models default to. That sounds like a minor thing until you try to publish AI-generated analysis under your own name and realize readers can smell the bot in the first three sentences.
Claude also ships Cowork, which one 2026 review called "the most capable agentic system right now for non-developers." Cowork handles multi-step tasks, research a topic, draft a report, format it, export it, without requiring the user to chain prompts manually. It is, in effect, a junior employee that doesn't need sleep.
But Claude has limits. Its context window is enormous, 200,000 tokens on the high end, but the model can stall on highly structured data tasks that involve tables, spreadsheets, or multi-sheet financial models. It also lacks the native search integration that makes Gemini dangerous for research-heavy work.
Gemini Owns the Research Stack
Google's Gemini, now shipping 3.5 Flash as its default model, does something neither competitor can match: it reaches into the live web and pulls back verifiable sources with citation links baked into every response. For analysts, journalists, and researchers who cannot afford to trust the model's training data alone, that changes everything.
A financial analyst synthesizing enterprise semiconductor capital expenditures can prompt Gemini to cross-reference SEC 10-K filings, TSMC wafer pricing schedules, and recent quarterly earnings transcripts. The model retrieves and grounds its synthesis directly in timestamped primary citations that an auditor can inspect independently. While competing models offer web-browsing integrations and retrieval-augmented knowledge bases, Gemini's deep integration with Google's real-time web index yields significantly lower retrieval latency on fast-moving corporate intelligence.
Speed is Gemini's second weapon. On coding tasks that require rapid iteration, write a script, test it, fix the error, rerun, Google's model returns responses in roughly half the time of Claude Opus 4.8. That advantage compounds over a four-hour debugging session.
Meanwhile, the global shift in where AI workloads run is worth noting. As more companies move inference and fine-tuning away from centralized hyperscalers, the quiet migration of data away from big cloud providers reshapes which models are practical for which use cases. Gemini runs on Google's infrastructure natively. That can be a feature or a lock-in, depending on who you ask.
ChatGPT Refuses To Be Pigeonholed
OpenAI's ChatGPT, running GPT-5.5 Instant by default as of mid-2026, took a different path. Instead of optimizing for a single strength, it built the widest ecosystem. Six new enterprise plugins shipped this year covering data analytics, creative production, sales, product design, equity investing, and investment banking. Partners include Wix, Replit, and Figma.
ChatGPT remains the most generalist tool of the three.
It can draft a marketing email, debug a Python script, analyze a CSV, and generate an image using DALL-E 3, all within the same session. The model picker now lets users switch between GPT-5.5 Instant, GPT-4o, and the o1 reasoning model depending on task complexity.
For strategic analysis, the kind of work where you need a model to weigh pros and cons, consider edge cases, and produce a recommendation with caveats, ChatGPT still leads. One comparison noted that for "strategic analysis tasks, ChatGPT was the top choice." The Pro tier, at $200 per month, unlocks unlimited access to the advanced reasoning mode that handles multi-step logic problems other models stumble on.
But ChatGPT's versatility comes with a cost. The model can feel unfocused. It tries to do everything and occasionally does none of them with the polish Claude brings to writing or the rigor Gemini brings to research.
The Blind Test Nobody Talks About
The 134-person blind test settled one question decisively: for prose quality, Claude is the default. But that test measured outputs from a single prompt type. Real work does not work that way.
A separate evaluation of coding performance on SWE-Bench, the standard benchmark for software engineering tasks, tells a more fragmented story. Claude Opus 4.8 scores 88%. GPT-5.5 hovers nearby. On AIME math competition problems, both models approach perfect scores. The gap that used to separate these models on hard technical tasks has nearly closed.
Where they still separate is on subjective dimensions: tone, structure, citation quality, and the ability to follow complex, multi-part instructions without losing the thread.
Pricing Has Settled Into Three Anchors
The AI subscription market now has three clear price points: Free, $20 per month, and $200 per month, according to a 2026 pricing analysis. Every major provider runs at least four consumer tiers.
At $20 per month, Claude Pro gives access to Opus 4.8 and Claude Code. ChatGPT Plus offers GPT-4o with limited access to advanced reasoning. Gemini's $19.99 Pro tier includes 3.5 Flash and full Google Workspace integration.
The $200 tier, ChatGPT Pro and Claude Max, unlocks unlimited usage and priority access. For heavy users, the math works. For occasional users, the free tiers are genuinely capable, though rate-limited.
A Practical Decision Tree
Three scenarios, three recommendations.
- The Technical Writer and Editorial Strategist: Choose Claude for superior stylistic variation, syntactic cadence, complex code refactoring, and minimal boilerplate phrasing.
- The Deep-Stack Researcher and Document Auditor: Choose Gemini for its million-token context window that digests full quarterly filings, massive codebases, and audio recordings with live web citation grounding.
- The Multimodal Generalist and Workflow Automator: Choose ChatGPT for multi-step algorithmic reasoning, spreadsheet analysis, and broad integration with third-party consumer workflow tools.
The question that remains unanswered is whether any of these models will meaningfully improve at tasks they currently struggle with, handling ambiguity, admitting uncertainty, and knowing when to say "I don't have enough information to answer that." The benchmarks keep climbing. But the ceiling might not be technical.
Comments (0)
No comments yet. Be the first to share your thoughts.